Category: Programming

  • Mid-October Update: Blender 3D “Badge Engineering” Project Underway

    Mid-October Update: Blender 3D “Badge Engineering” Project Underway

    This month’s update is vastly more successful and Blender-oriented than the previous few; instead of just engaging in long back-and-forth chat conversations and never really getting anywhere with a model, I’ve finally completed my first small Blender/BeamNG project: adding a missing badge to a vehicle mod.

    A couple weeks ago, while looking for new and interesting real-vehicle mods to try out in BeamNG, I downloaded the 2011-2014 Dodge Charger mod by the popular creators Flanje and NMG. Being a mod from ModLand, I didn’t have high expectations for the quality or accuracy; however, I was somewhat surprised when the vehicle loaded in-game looking pretty close to the actual vehicle. The interior was mostly well-modeled, the exterior was accurate, and there were no glitching parts.

    However, there were a few big problems. First, the sound was completely wrong (which is a totally separate small BeamNG engineering project I completed last week), and second, there were no badges beyond the standard “Charger” and “Dodge” lettering on the trunk. While this wasn’t a huge gameplay issue, it seriously broke the immersion when you loaded in a stock R/T configuration and there wasn’t any R/T badge on the trunk. Why would a modder go to the trouble of modeling most of the other standard badges on the vehicle, but leave out a few random important ones?

    Modeling the R/T badge

    This became the premise for my next big Blender project: “finish the modder’s work” by modeling the other badges, including the R/T badge, the HEMI side badge, and potentially the SXT/SRT8 trunk emblems as well if I had time. I started last Monday (October 5) by pulling down some reference images off of sellers on Ebay, finding straight-on shots of the R/T badge first, since that was my top priority. I actually found a pretty good image without too much digging, which (unfortunately) I’m not sure I can say confidently about the other badges. To ensure that I was going to create a badge sized correctly, I got the actual dimensions of the R/T badge and scaled the image such that the badge in the photo matched those dimensions.

    So I was able to get started pretty quickly in Blender; to begin tracing the badge in the software, I didn’t hunt for custom fonts or try to type out the letters and the slash, because that would be way too imprecise. I found out that the better solution for modeling a badge is to start with a Bezier curve, which allows you to place vertices at key points on the badge and connect them via a curved line. This sounded like a great setup for the R/T badge, so I Ctrl+right-clicked on the corners of the R, slash, and T to get a total of about 27 vertices (81 with the triple baking).
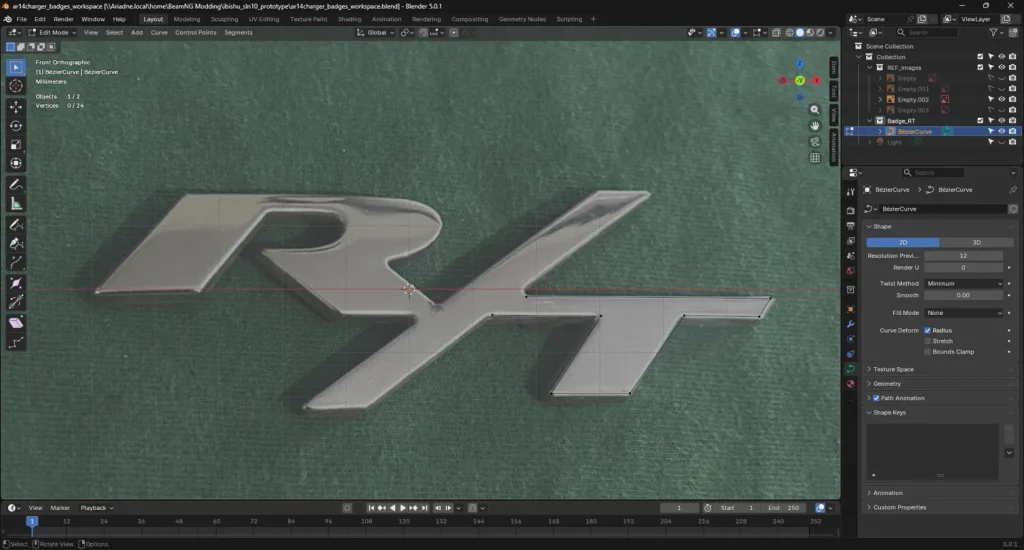
    The early stage of the project, with eight true vertices created around the edges of the “T”. Currently, the badge displayed is the reference image only.

    Once I had vertices in for all of the important corners of the badge, it was time to smooth the points around the bowl of the R, as they were quite jagged to start due to not enough resolution. To do this, I added additional points to the arc around the bowl via a Subdivide operation, moved them onto the lip, and spaced them out equally to ensure that the curve traced the bowl properly. This was the most tedious step of the process, as it required ultra-precise mouse movements and constant tweaking as points gradually got out of line. I spent about a day on this step (likely Tuesday by now) before I got to the smoothed-over version of the R, shown below with the curve in solid form:
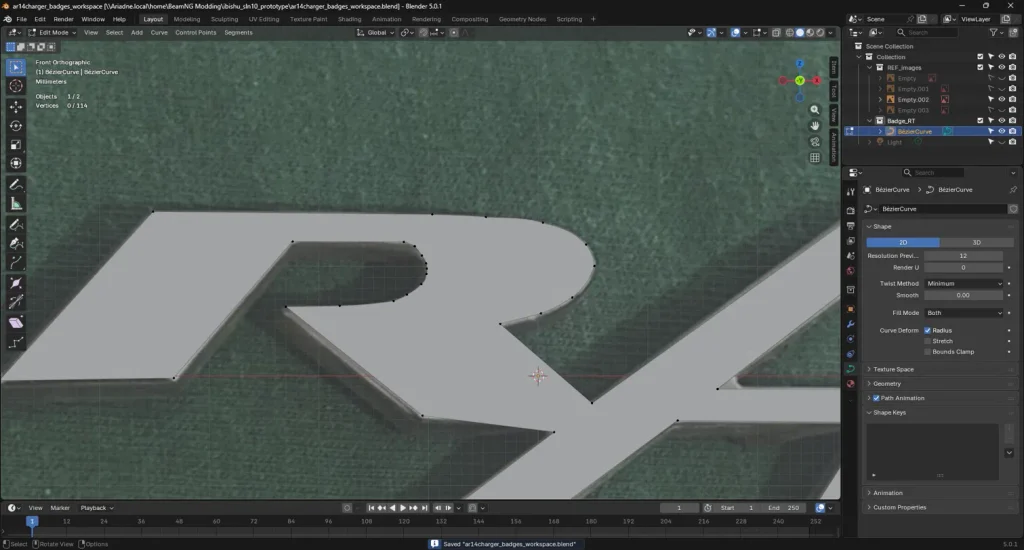
    The completed curve on both the outer and inner portions of the “R”, with the Bezier curve now shown as solid.

    Now that the curve was relatively smoothed-over (with a couple more areas to correct before the next step, which I’m sure you can identify from the above photo), it was time to ditch the reference image and convert the curve to a mesh. I honestly wasn’t expecting much at this point, since I had been working solely with that image and had no real experience seeing what this transformation would look like. However, I was quite surprised when I changed it to a mesh and discovered that the badge actually looked pretty convincing. To ensure that the depth (or thickness) of the badge was correct, I extruded it by 1.5mm, and confirmed that it looked accurate afterwards. The result of this is shown below.
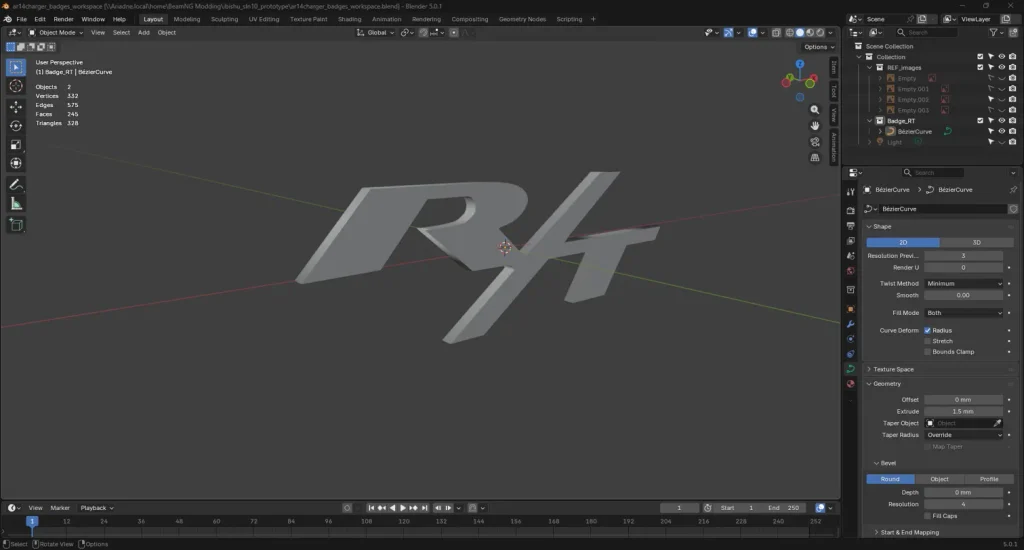
    The meshified and extruded badge, with some minor corrections made around the slash area. Looking pretty accurate; for comparison, see that green reference image at the top.

    After this step, I performed some quick checks on the mesh (Non-Manifold, origin and position verifications), and moved into the UV-mapping/shading phase. The badge should obviously be chrome, but to get to that part, I first had to apply a Shade Smooth by Angle modifier to ensure that the chrome wouldn’t be bent or reflected in odd ways to the jagged edges on the tip of the T, for example. I applied the modifier to 30 degrees to ensure that nothing seemed too subdivided still. I also generated a simple UV map of the badge in Blender, resulting in an interesting-looking diagram of the islands and squares representing the different caps of the badge.

    To actually apply the material, I used the already-existing chrome material provided by the mod, which had been used for the “Charger” left-side badge and the “Dodge” lettering. I simply went to the Materials tab in Blender, added this new material (ensuring that the name matched exactly with what was in the mod’s materials.json file), and turned up the Chrominess setting. Nothing changed in the viewport, of course, since the chrome material would only be rendered in-game, after export. At this point (this was around Thursday/Friday), I was pretty much ready to export the badge. However, I observed an issue with the bowl of the “R” just before doing so: there was still a slight facet on the bowl, making it appear as if it had been creased (shown below).
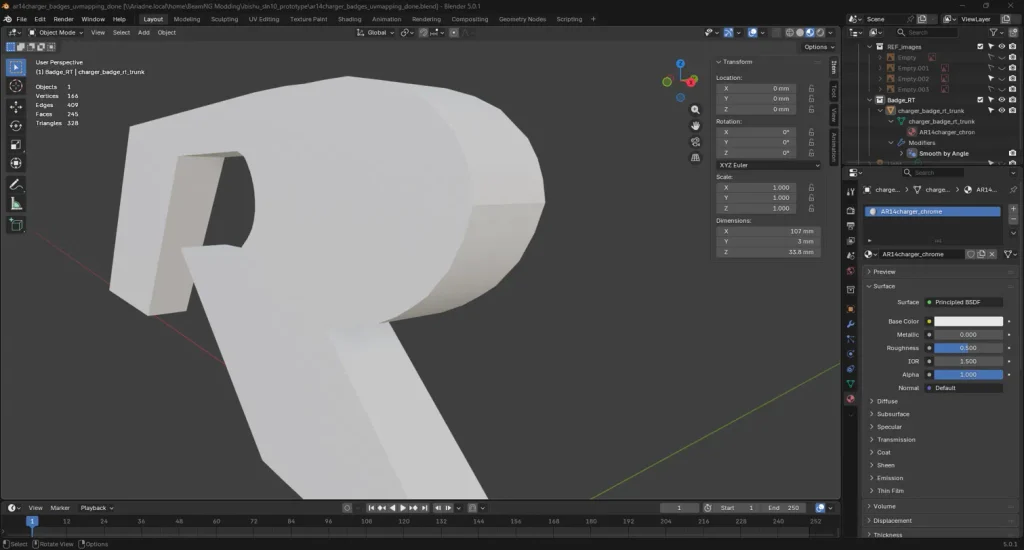
    The slight facet on the bowl of the R–this is what “cause for concern” looks like in case you’re doing something similar. On the right-hand pane, you can see the chrome material has been added.

    While it might not be so noticeable in-game, there was a possibility it could mess up the chrome reflections, as with previous issues. To fix it, I raised the angle on the “Smooth by Angle” modifier to 45 degrees, and the facet disappeared. I also turned on the “Ignore Sharpness” setting, which improved the result even further. With this change completed, I baked (applied) the modifier, hid the reference objects (they’ll have their time later!) and exported as a .dae file for BeamNG.

    Sidenote: If you’re wondering how in hell I got Blender 5.0.1 to export a .dae file, which was supposedly discontinued many major versions ago, here’s the answer. I’m using a custom Blender add-in from the BeamNG modder Grille, which adds the ability to both import and export .cdae/.dae files. This is a vital tool for modern BeamNG modders looking to use the latest Blender versions, since the Blender developers have thrown native .dae support in the trash can and never looked back.

    With the badge exported, there was only one phase left before it could have a chance of appearing on the vehicle in-game: the coding phase.

    Setting up the JBeam files

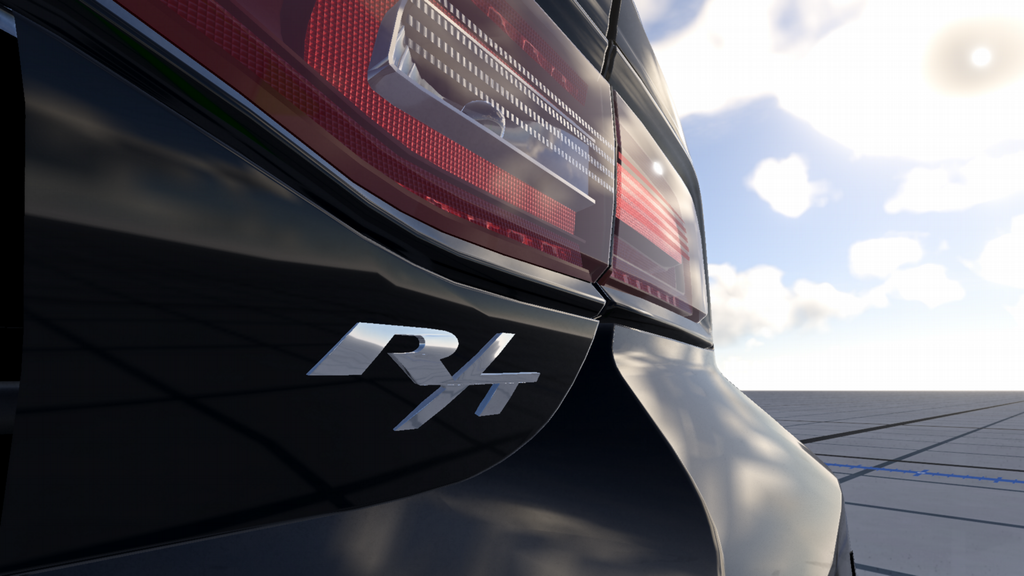
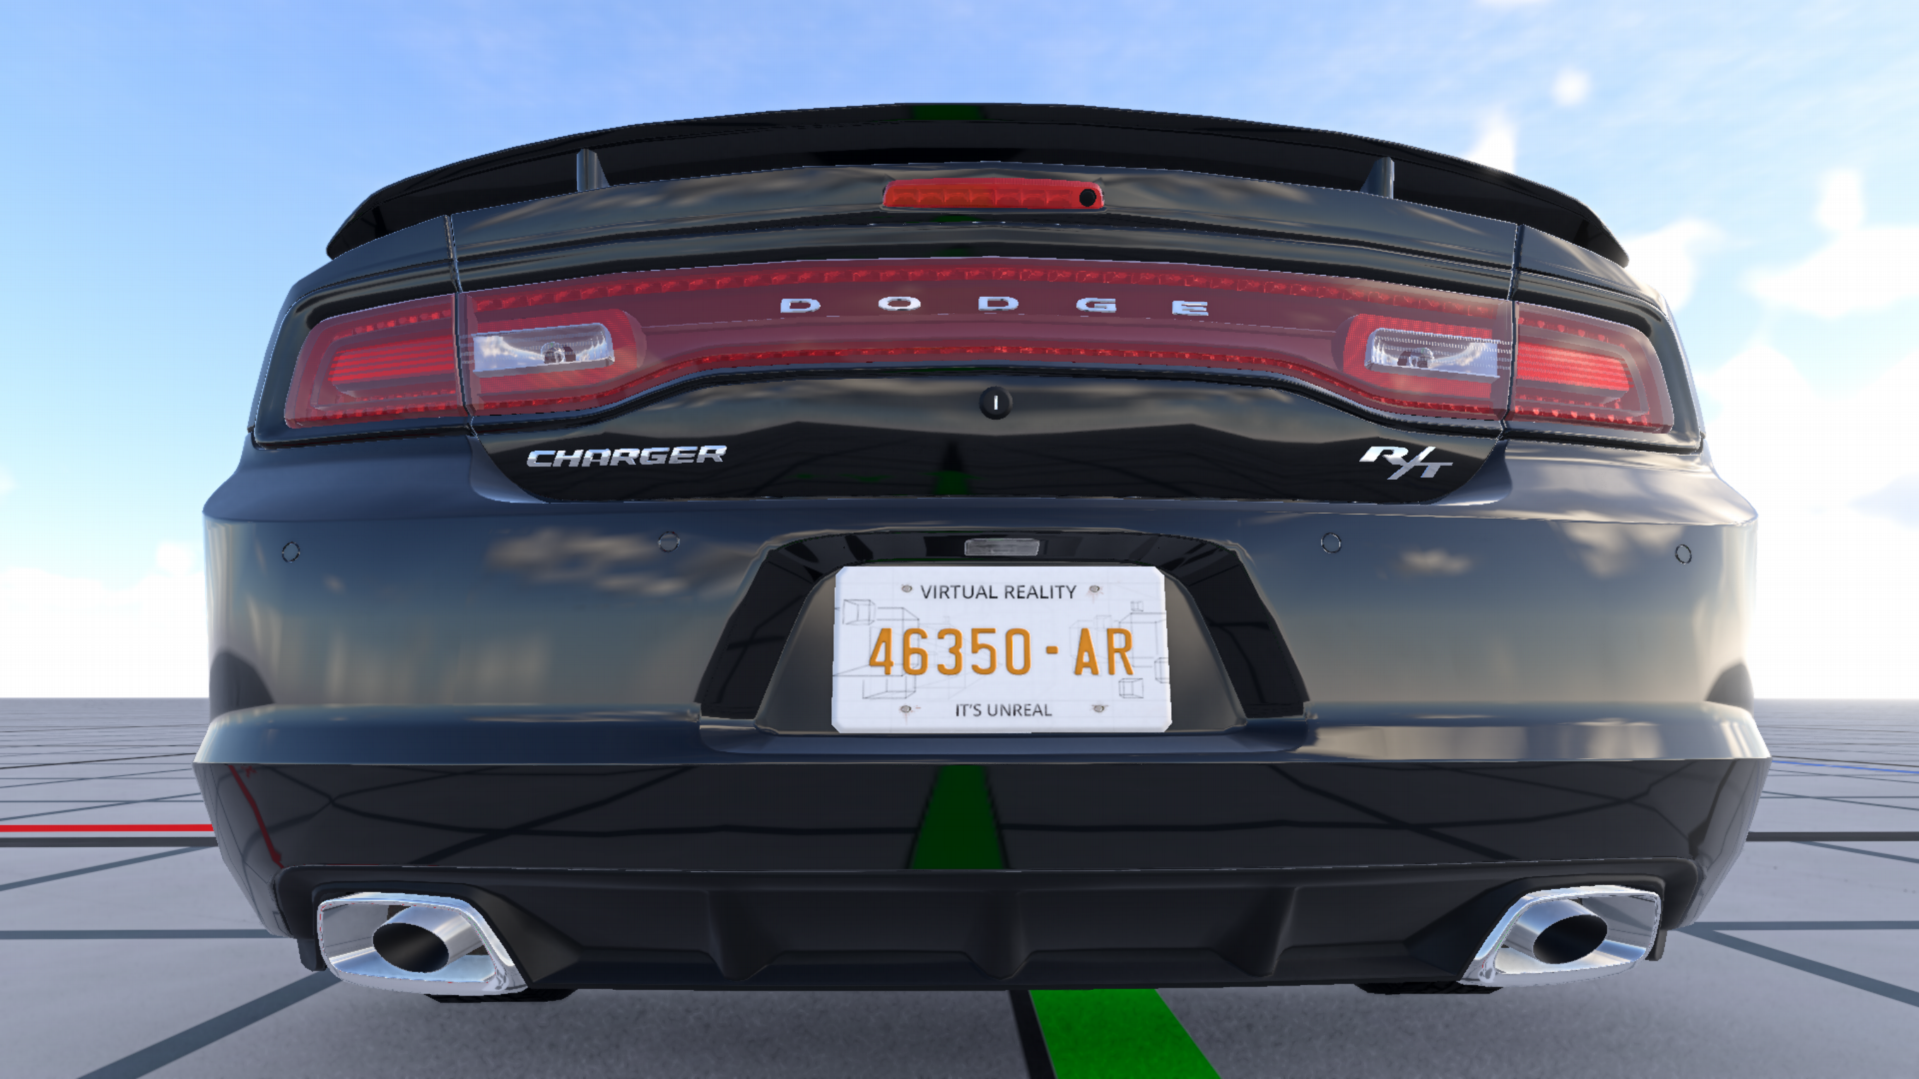
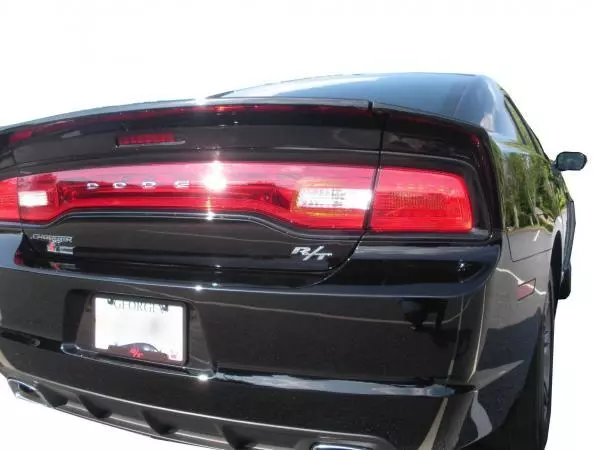
    To ensure that BeamNG recognized the badge’s existence and put it in the right location, I added a simple line to the mod’s Trunk jbeam file, since that’s where the badge ends up going. (See below for a real-world image of the 2011-2014 Charger R/T’s trunk lid).
    This line would add an additional component to the trunk, called “charger_badge_rt_trunk”, map it to the trunk part, and set the pos and rot values for the badge (position and rotation). The line was hardcoded in the flexbodies section of the JBeam file; my future goal is to have the badge set up as a slot in the vehicle configuration menu so you can choose to apply the badge or not. I used some dummy pos numbers at first before loading in the game, just to see how it would load in. Surprisingly, those guesses weren’t far off, but there were a couple of problems.
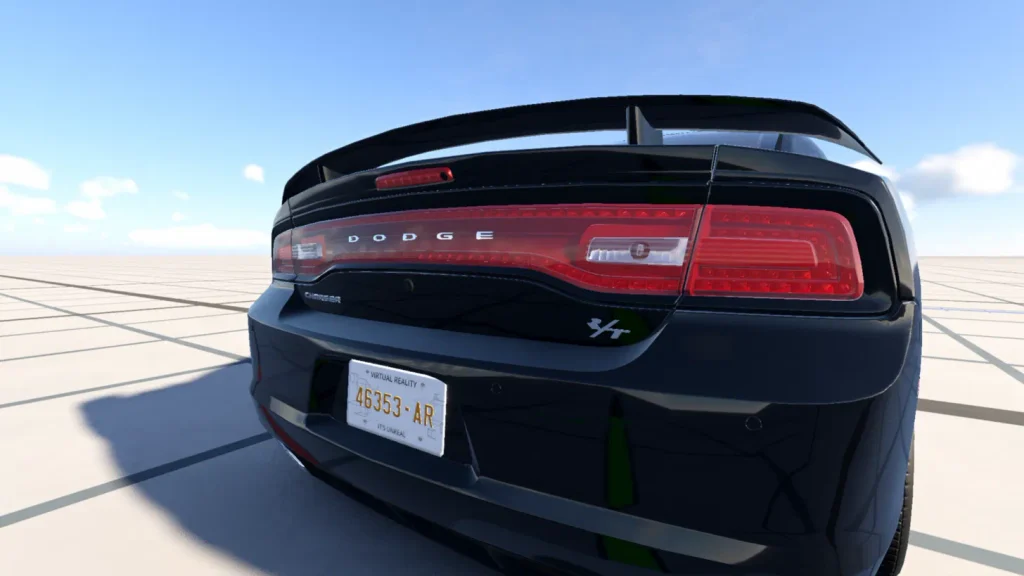
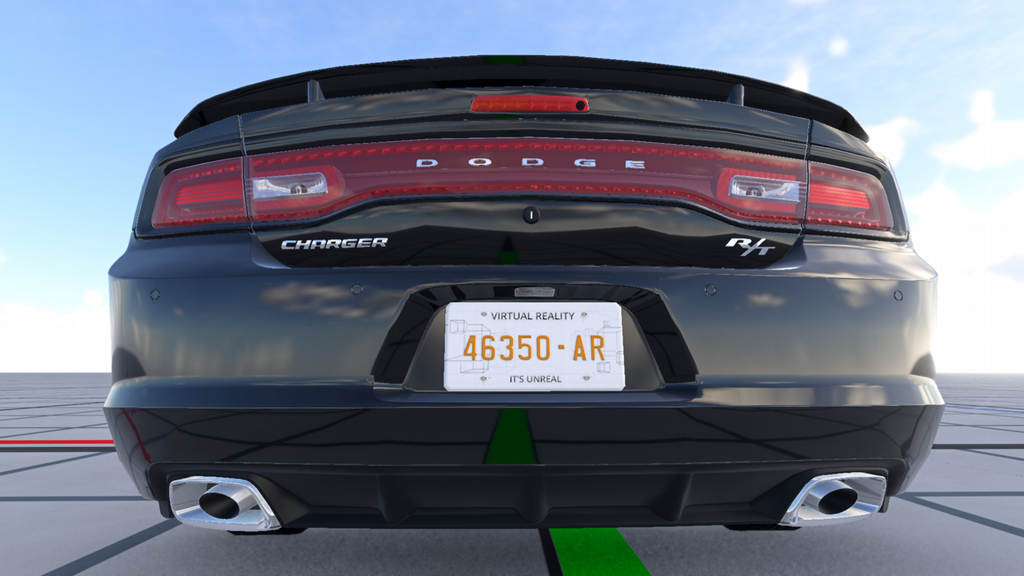
    The R/T badge having been loaded into the vehicle “successfully”. Can you spot the issues? (They’re quite obvious).

    Well, first of all, the left edge of the R was clipping through the trunk material. Second, the badge was positioned a little bit too low; in the real-world image above, you can see it’s a little bit closer to the bottom edge of the taillight. I thought these were going to be simple position issues–and they technically were–but it took over an hour of constant tweaking and screaming back and forth between Blender and BeamNG to get it to look correctly-positioned. The result of this intermediary screeching is shown below:
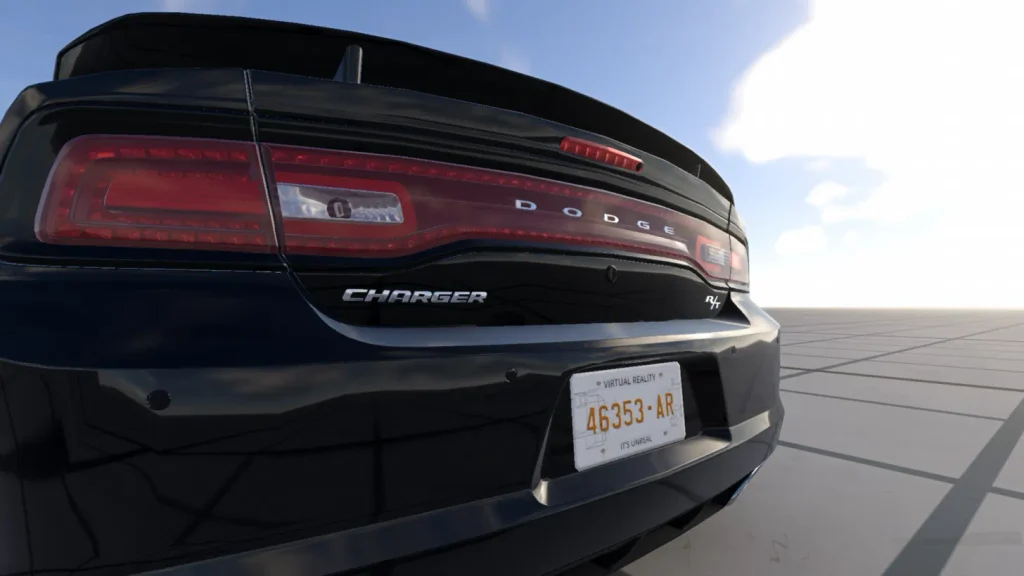
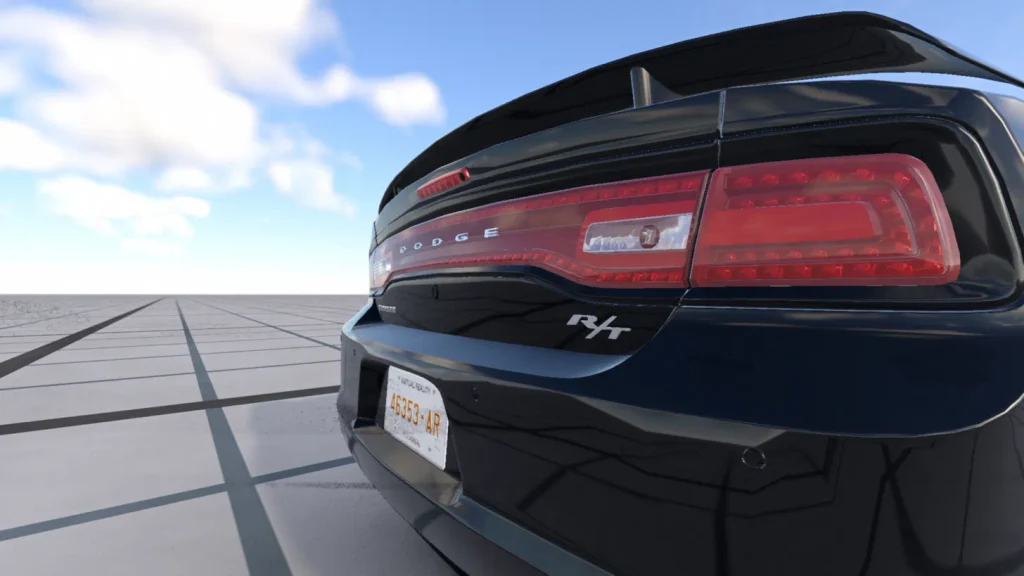
    Now, you might be noticing something about this current badge. While it looks pretty convincing (and probably wouldn’t raise any suspicion when viewed from a greater distance), it also looks a little flat and dull from certain angles. Of course, this is a game, and the reflections can only go so far, but when comparing the appearance of the R/T badge to the Charger badge on the left, there’s a slight difference in the roudedness, or chrominess, of the badge. I noticed this as well after the preliminary tests; to fix this, I ended up applying a 0.5mm bevel/chamfer on the badge via Blender.

    However, I worried this wouldn’t be enough. Even previewing the badge again in Blender, it seemed that it didn’t really change all that much (although the numbers and statistics in the upper-left corner directly confirmed that something had happened). So I went with a different strategy: apply a bend to the badge so that it sticks out in the middle region vertically, and curves outward to match the flow of the trunk lid. I hoped that this would help it capture a bit more of the gloss, as I noticed a similar kind of bending on the Charger badge upon close inspection. I used Blender’s Simple Deform modifier to make this change, doing one on the X-axis and one on the Z-axis. The X-axis curve went to an angle of about 15 degrees, and the Z-axis I kept at 8 degrees, since I noticed some strange streaking/chrome aberrations on the surface due to the competing bends if I went too far above that.

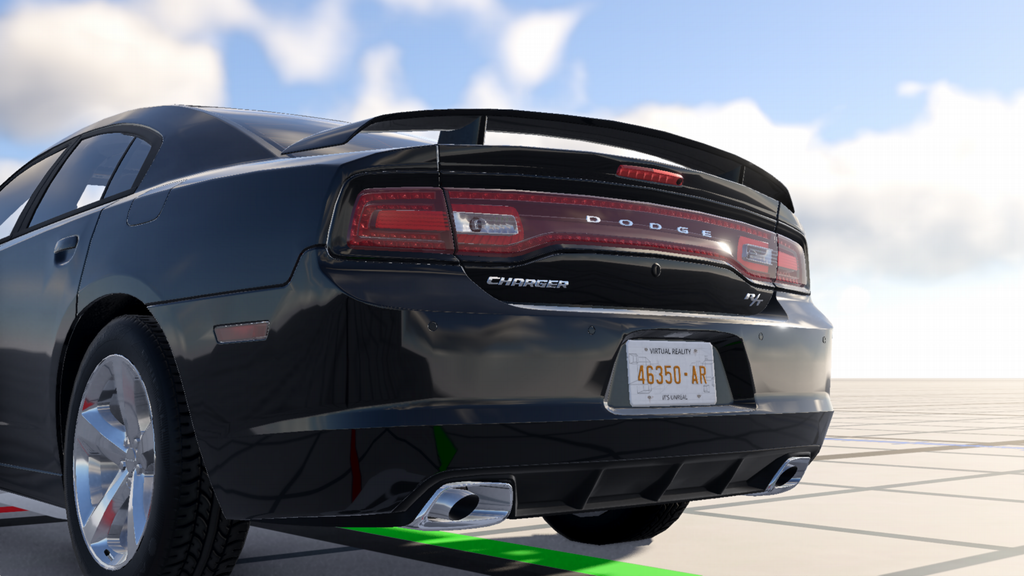
    After re-exporting the badge and loading it into the game, I realized that the change had made a significnat improvement. These photos can’t really do justice here due to their smaller size and WordPress compression, but in-game, they looked quite a bit better than the initial pass.
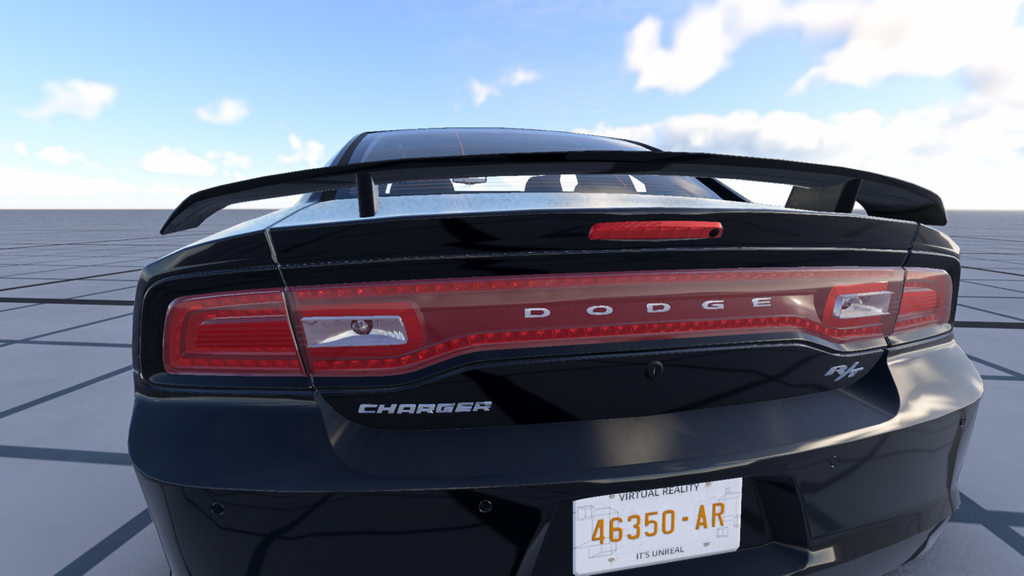
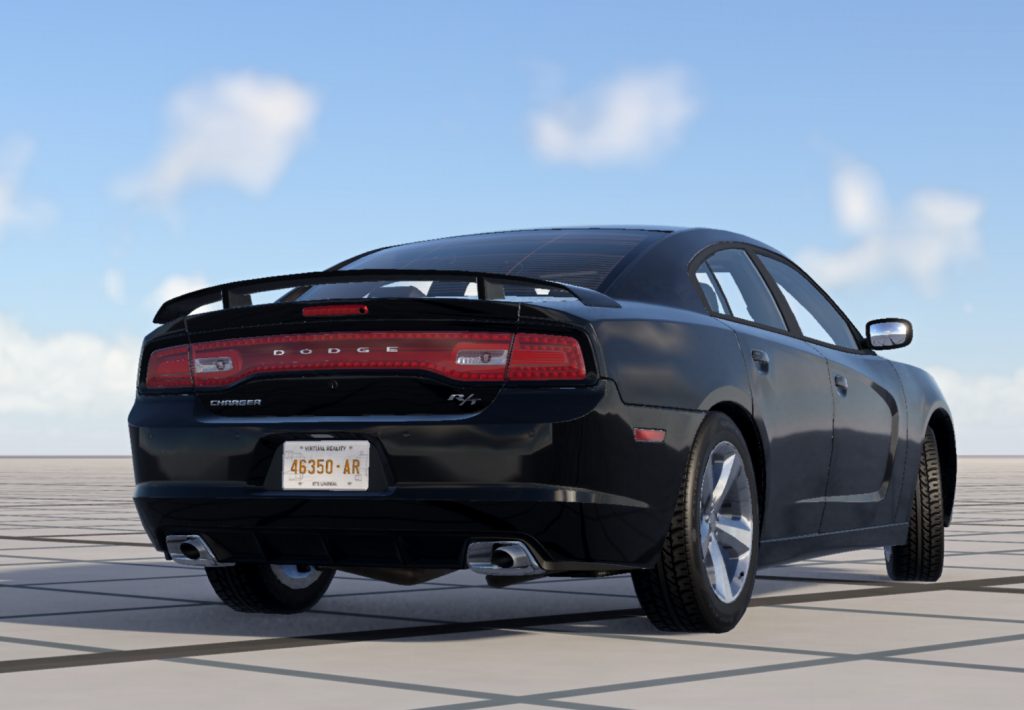
    And with that, I approved the final version of the R/T badge, saved all the changes, and closed out of the first badge-modeling phase. From a distance and close-up, the badge looked more than convincing: the reflection and bevel on the model worked wonders for the chrome appearance. I’ll now be taking some more natural photos in an actual map (not the Gridmap testing area), such as the parking garage in West Coast, USA.

    Next steps

    While the logical next step is to start working on the HEMI side badge, there is an additional thing that I’d like to ideally take care of before I get the HEMI badge into the game. Right now, the R/T badge loads onto the vehicle no matter what configuration you choose; there’s no taking it off since it’s hard-coded into the flexbodies section of the trunk JBeam file. I’d like to find a way to create an additional slot in the Vehicle Configurator, something like “Trunk Trim Lettering”, that allows you to choose between Empty, R/T, SXT (potentially), and SRT8 (potentially). This would be a more coding-heavy undertaking, which can become quite problematic in BeamNG due to the strict syntax requirements, so we’ll see how that goes.

    The reason why I’d like to have that done before the HEMI badge goes on is I don’t want the two badges to start competing and causing conflicts if I have to hardcode both of them onto the vehicle. It would be better to have a slot for the side badge and a slot for the trunk badge, which is the accepted convention for BeamNG mods.

    Well, as this “badge-engineering” project gets further underway, and I start working into the side badge as well, I’ll post more updates and photos on here throughout the process. Hopefully things won’t fall apart once things start getting vastly more complicated–the black edges on that HEMI badge look quite difficult. Stay tuned for more info!
  • September Update: Portfolio Sites, AI Reboot & Alternate Reality

    September Update: Portfolio Sites, AI Reboot & Alternate Reality

    Welcome back to Discordant Harmony! It’s been a few weeks since the last update, but I’m now back with the September update on how various projects have been going. In this blog, I’ll discuss a new alternate reality game/narrative I’m working on, some new video editing projects, and new AI/machine learning endeavors including the Painting Classifier AI Project and Quarto sites.

    AI, Machine Learning, and Portfolio Sites

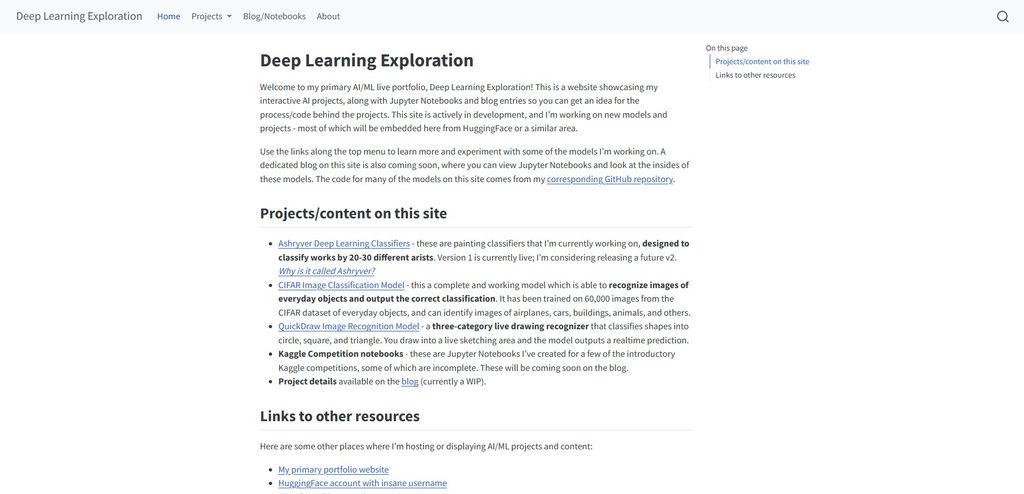
    The homepage of my new Quarto portfolio site for active model experimentation

    First up, I suppose, will be my various attempts at restarting the machine learning projects I’ve been working on. They have been sitting around for a couple of months now, ever since fast.ai broke something in their code and prevented users from building anything back at the end of June. Those issues have now been fixed, and I’ve moved away from trying to use the deprecated fastpages anyway to host live versions of my models. Instead, I discovered the much better successor to fast.ai called Quarto, which allows you to host Jupyter Notebooks, blogs, and model embeds through GitHub Pages.

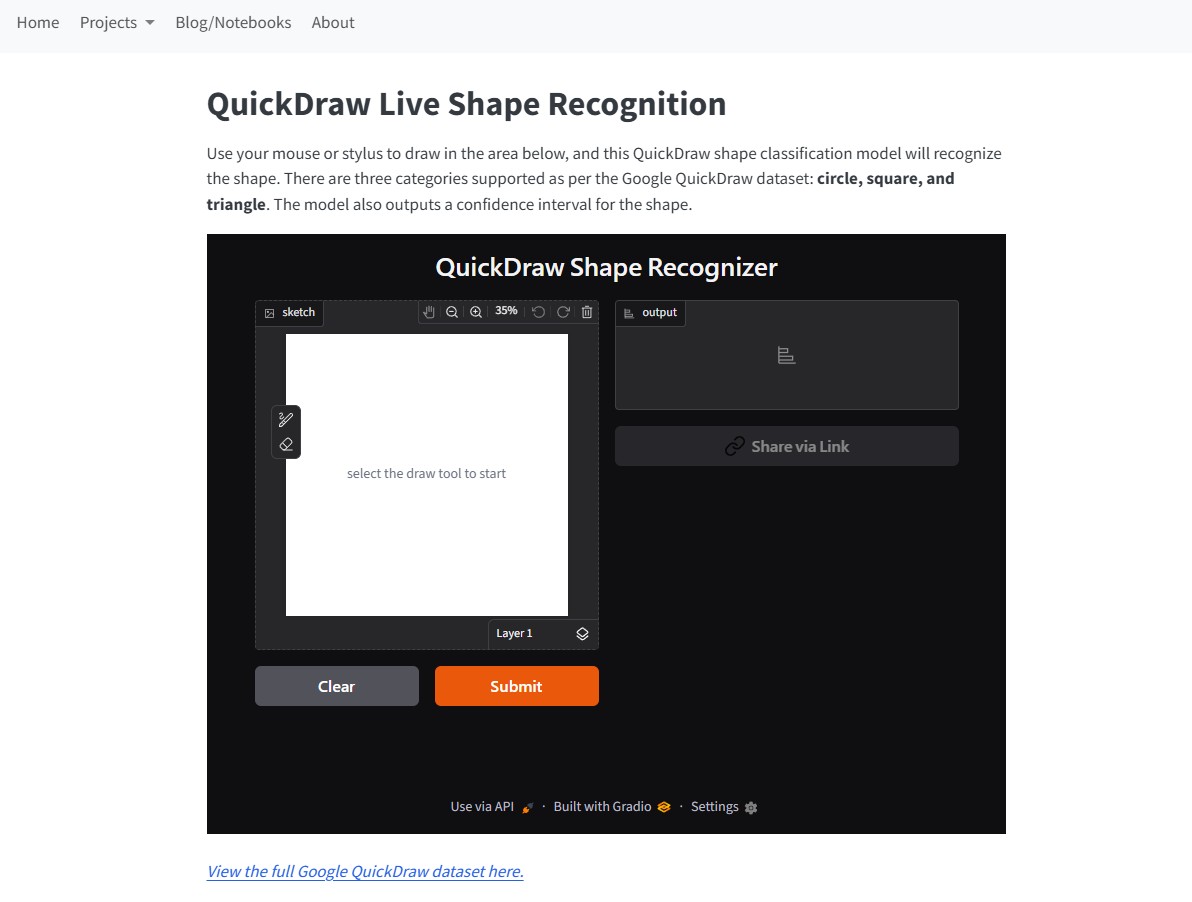
    This is what I’ve been working on over the past week. I now have a live, working Quarto portfolio with the latest Ashryver Painting Classifier (via a HuggingFace embed) and, finally, the CIFAR-10 Image Classification Model I trained last year, during the inset event. Additionally, I’ve put up the QuickDraw Shape Recognition Model that I recently refurbished from August 2025, and it worked surprisingly well with the Gradio Sketchpad integration on HuggingFace. This is something that I’ve been working towards for quite a while–back in June, I stated that I was “really trying to move away from models that exist only within a Visual Studio Code window and require extensive amounts of effort on the part of the user to get it working on their own machine.” Well, that move has finally been made.

    As of Thursday, I now have a working blog set up on the Quarto site, where I can add posts containing notebooks, code snippets, and anything else that allows me to do detailed data storytelling and visual analysis. The Quarto interface is a little bit clunky behind the scenes–you have to deal with both a .qmd page and an .html page and update both whenever you want to insert a blog. However, it’s much better than alternatives like Netlify or the deprecated fastpages if you want to showcase personal models (not production-ready content) and post blogs containing Jupyter Notebooks.

    At the moment, I have no plans to host any of these models on large, production-ready sites like Vercel or ChatCode. This may come later if I find that I need more hosting space or interaction with users, but for now Quarto works perfectly fine for displaying these projects so people can actually use them. I’ve heard that Quarto is highly flexible when it comes to inserting runnable notebooks, which is something that’s pretty important for the kind of work I’m doing right now. And the process for uploading the models to Quarto really wasn’t so bad: all I had to do was get the .h5 or .keras model files, upload them first to a HuggingFace/Gradio space, and then link that space as an embed to the Quarto site.

    Now that the Quarto site is pretty much done for now, I’ll be looking at (perhaps) designing a custom interface for the HuggingFace embeds, using HTML and JavaScript, so that they can look a little bit better. There’s nothing wrong with them now; however, for the future, it may help if I have even more of a flexible interface. Then, it’ll be straight into Unit 3 of the Practical Deep Learning course. There isn’t any need to continue interating on the painting classifier right now; it works perfectly fine and it’s already been three months since I started the second unit.

    I noticed that fast.ai’s Practical Deep Learning for Coders course is woefully outdated in several key areas; notebooks do not work, workspaces are deprecated, and packages are broken entirely. If this becomes prohibitive as I continue to work through the course, I may switch away from this and personally explore some other ML topics. At the same time, I might start a new Intro to Machine Learning course on MIT’s Open Learning Library; most of the content will be a review but it’s good to make sure I’m not forgetting the fundamentals, anyway.

    The Alternate Reality Project

    “Olivia’s relationship with her brother can best be described as intimate, careful, and at times, playful…she very rarely becomes outwardly upset with other people, [but] will sometimes rant about frustrations to her brother behind closed doors.”

    — the Episodic Alternate Reality Narrative, volume 01

    I’m guessing that you’re wholly gobsmacked by the above quote. After such a serious, concrete discussion about machine learning models and AI courses, we have . . . what?! A paragraph that reads like it’s from some kind of elaborate personal databse file? No, fear not. This is simply one of the opening sentences of my latest undertaking, the episodic Alternative Reality Narrative, Volume 01, or e-ARN 01.

    What is it, exactly? Consider it a space where I’m experimenting what life woud be like now (and in recent times) if things had gone very differently many years in the past. In the narrative, I’m writing prose, third-person descriptions, or brutally-honest observations on life in what I like to call the Alternate/Augmented Universe. Every section and every account in the narrative is designed to sound as real as possible, although it of course is only fiction here in the Prime Universe. Detailed narratives are engineered to read like lengthy Ready Writing prompt responses, except without a clear direction and more focused on the presence of our new alternate-reality character.

    And, because this is a bit more than just a narrative, I have created additional artifacts (such as online, for example) that complement the project. Most notable is the Fuzzy Thoughts AoPS blog, which I recently created alongside my prime-universe random ramblings blog as the official writing site of our alternate character. As our character (codenamed claudaroo in the alternate universe) is extremely busy, posts only happen once or twice a week. However, having a dedicated alternate-universe blog allows me to more precisely craft a new character, showcsae their interests, and engage in fictional back-and-forth conversations with them. (There is no other person on the other side of the computer screen, of course. I’m merely playing both sides of the field; skronkmonster is wholly responsible for the creation of the blog).

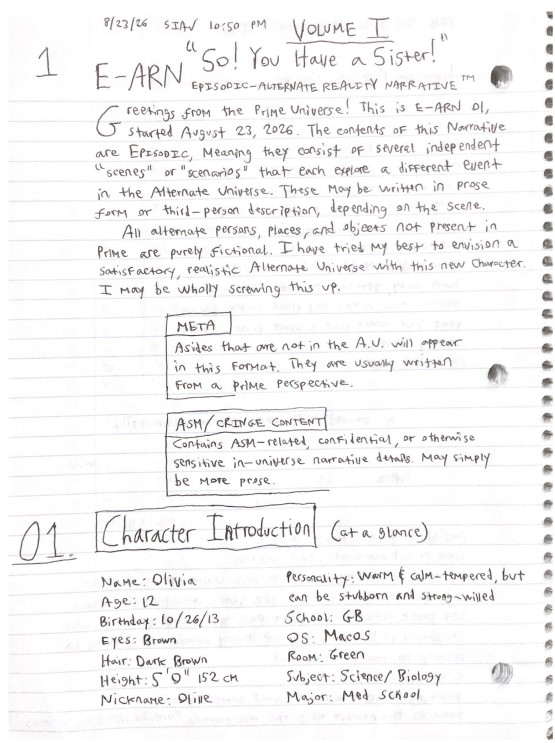
    My plan is to focus on the handwritten narrative format (yes, handwritten) and progress through several volumes of the e-ARN 01 to fully develop this character. Why handwritten, you ask? Simply because I feel that I think more creatively while in bed, poised over a notebook and determined to uncover what, exactly, life would be like in this very different Alternate Universe. It’s sort of like superimposing a brand-new individual on top of your everyday adventures, which can be both enlightening, fascinating, and frightening all at once. Shown below is the cover page of volume one, which is currently in progress and set to take up about twenty-one pages. (This all appears in the official SIA Time Capsule Notebook).

    The title says it all (no inferences required). I will, of course, be scanning all twenty-one pages into a secure location on the DiskStation and the Google Drive once volume one is complete.

    Stay tuned for further information on this up-and-coming alternate reality project. It’s one of my most unusual undertakings yet, and I’m excited to see where it goes.

    Other Projects

    I’m sure there are a whole lot of other things that I’m missing, but one thing I can think of right now is Flames of Rebellion, Book 4. This project has been sort of put on hold, as the AI stuff has taken the center stage and several new submissions and competiton applications have been taking place. That’s not to mention the Labor Day Animal Concert coming up next week, and several new jazz-related musical compositions that actually tie in closely with the alternate reality narrative (yes, everything seems to come back to that lately). So I’m letting the machine learning, the BeamNG.drive video editing, and the various short stories I’m working on take the stage, because Flames of Rebellion doesn’t really have too much of a deadline. (I’d like to try to finish the series before Int-Offshore 2027, but I think that’s pretty unlikely at this point).

    I’ve now been a member of the BeamNG Roleplay subreddit for almost four months, which is pretty hard to believe. I’ve not been as active on there lately, but after this weekend, I might have some new posts–and short videos to upload on the main BeamNG subreddit. I’ve been getting into the cutting-up side of BeamNG, and I’ve flagged a new map mod and traffic mod to download for more immersive cutting-up sessions. Bonus points if I can get the insane in-simulation motion blur to cooperate, because that really improves the realism of the whole environment.

    Well, that’ll be all for now. Don’t forget to check out the updated AI & Machine Learning Projects page, which now has new links and images. Until then, I’ll see what happens with all these endeavors!

  • Ashryver V1 Painting Classifier: Release Summary

    Ashryver V1 Painting Classifier: Release Summary

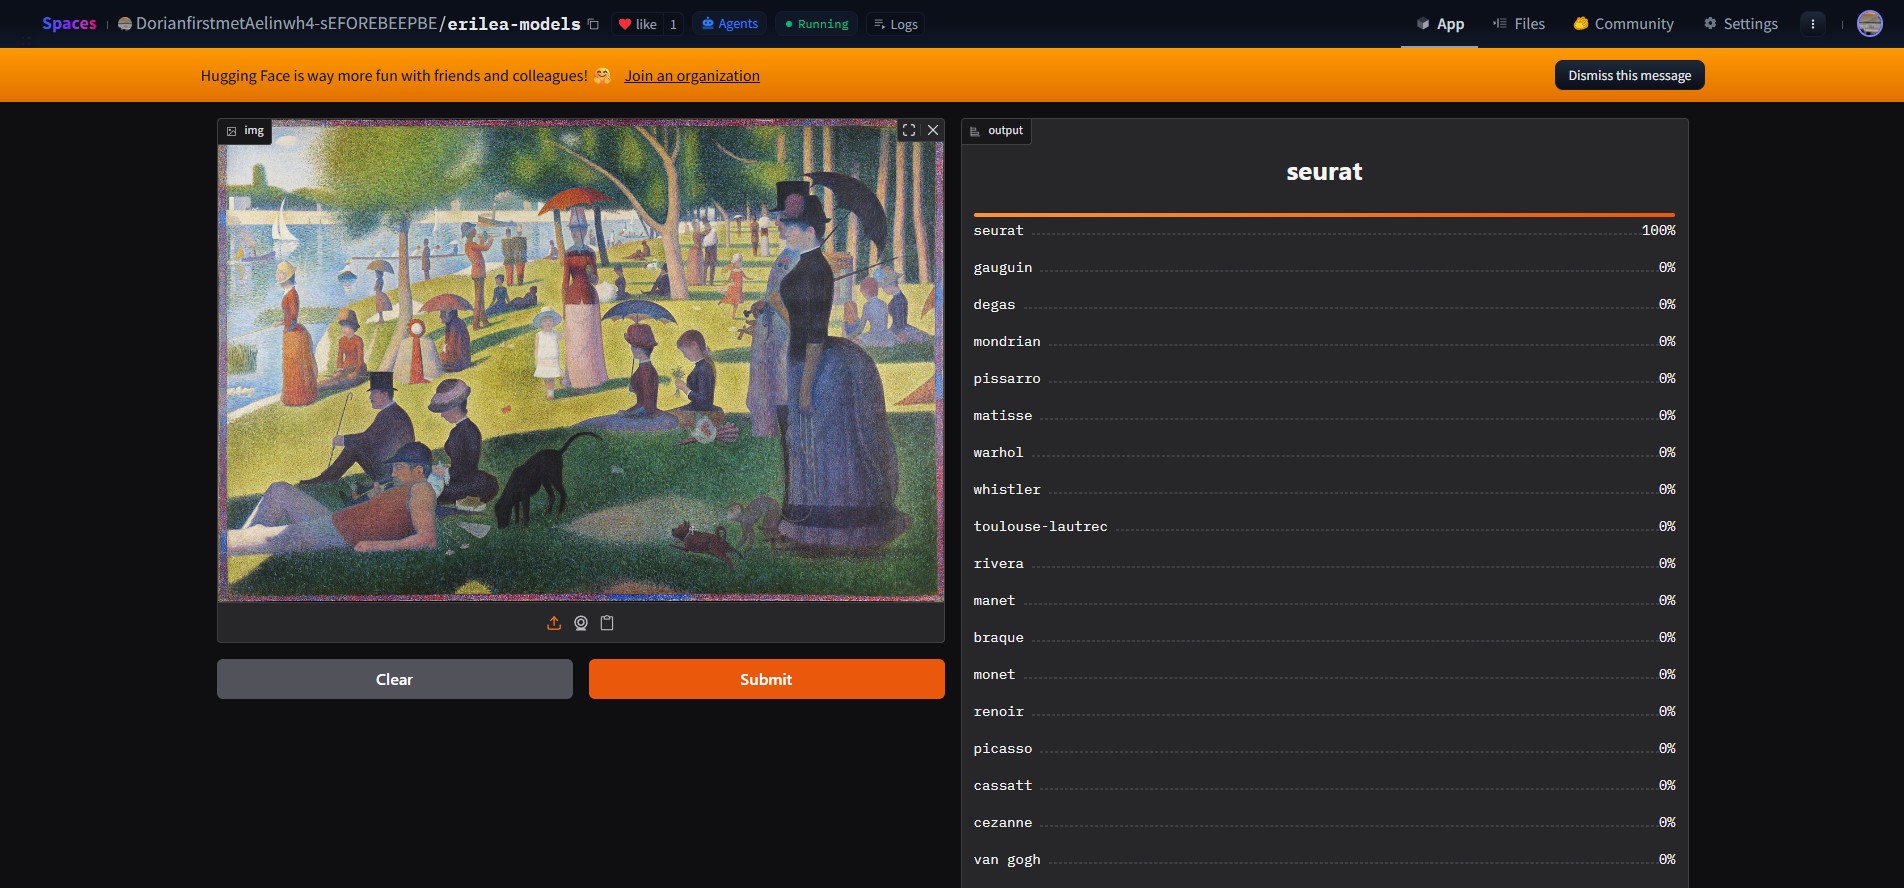
    Today, I finally finished setting up the Ashryver V1 Painting Classifier, my latest interactive web-based model, and placed a live embed on the AI, ML, and Web Projects page. You can now interact with the model right from your browser, and upload any painting you choose for the model to make predictions. Although the embed is a little small, and the formatting is still on the uneven side due to WordPress’s lack of flexibility, I hope to have these issues sorted out soon. Besides, my ultimate plan (perhaps once the final, non-prototype Ashryver V2 model comes out) is to place an active HuggingFace API instance of the model on one of my websites. I’ll have to wait until HuggingFace and Gradio sort out a CORS issue first, though, as there have been known issues across all platforms for the past few weeks.

    In this post, I’ll provide a brief summary of the training process, the overall model performance, and my future goals now that this project is “finished”.

    The Training Process

    I started working on the Ashryver V1 model about a week ago. I used the fast.ai foundational framework for this project, moving away from the clunky and cumbersome Tensorflow libraries I had been familiar with before. fast.ai is just an upper layer of Pytorch, which is the latest and most efficient machine learning library. I was blown away by how easy it is to instantly create and train a deep learning model; all it takes is just a few different code cells and some DataBlocks.

    As a brief reminder, this Ashryver V1 model is a painting classifier trained on images of 20 different Impressionistic and modern artists; I aimed for about 300-400 images per artist, yielding a total dataset of about 2,700 images (about 500 of which were split off for validation). Although this is a relatively modest dataset size, it ended up doing the job very well. I did have to go through several training runs to get the accuracy above its initial poor score of 0.60, but things turned out well in the end.

    At first I was using the resnet34 model, which was rumored to be exceptionally good at classifying paintings. This is one of PyTorch’s pretrained models, and it’s called resnet34 because it has 34 layers in its convolutional neural network. This worked out okay, but generally you want to be achieving higher than 0.60 validation accuracy for a classification model. So I decided to switch to the resnet50 model, which prefers an image size of 224 x 224 pixels and has 50 layers in its CNN. This model performed substantially better, first achieving an accuracy of 0.77 on the initial 1800-image dataset, and then 0.89 on the final 2700-image dataset.

    Once you have your data in the artist folders, this is all you need to do to train your model -- just two simple code cells.
    
    # Create the Datablock
    dls = DataBlock(
        blocks=(ImageBlock, CategoryBlock), 
        get_items=get_image_files, 
        splitter=RandomSplitter(valid_pct=0.2, seed=42), # split 20% of the data off for validation
        get_y=parent_label,
        item_tfms=[Resize(448, method='squish')]
    ).dataloaders(painting_data_updated, bs=32)
    
    dls.show_batch(max_n=20) # show a sample of 20 images that the model will be trained upon
    
    # Train the resnet50 model
    learn = vision_learner(dls, resnet50, metrics=error_rate)
    learn.fine_tune(4) # train for 4 epochs
    

    The Production Process

    Once I finished training the model and was satisfied with the result, I moved onto the production process. In the previous blog post, I touched on the difficulties I was having with HuggingFace in setting up a space for the model; I managed to resolve these issues a few days ago and get moving. The Ashryver V1 model (and any successive models) are running in a HuggingFace space, which I’ve set up and named ‘erilea-models’ to embody the fictional continent of Erilea. This space behaves somewhat like a GitHub repository, which you can clone down to your computer to add code and add models that can be represented using HuggingFace’s UI. All I had to do with this repository was drop in my pre-trained model in the form of a PKL file, and then call that file to make predictions using a simple notebook. That notebook then launched a Gradio interface (essentially what creates the graphical UI you see on the space itself) that allowed the model to make live predictions.

    This way, you don’t have to clone down the entire repository and install a bunch of insane packages to play around with the model. You can just go to the HuggingFace space (which I’ve made public), upload your own images, and have it make predictions. There’s actually even more I could do with this model, like using the Gradio API to place it on one of my own websites and use some custom JavaScript to make it look a bit different. However, the current HuggingFace solution works perfectly fine for this V1 model; I may consider switching to a more advanced API solution for V2.

    Next Steps

    Speaking of V2, let’s take a final look at my next steps for the Ashryver model. I’d like to improve the model’s reliability on Matisse paintings; right now it continually misclassifies Matisse’s tape drawing The Bees. I’m not sure how to deal with this one, as it isn’t a “painting” in the traditional sense, but users might still want to predict with that image. There have also been some isolated issues with other artists, where incorrect predictions crop up every so often.

    For V2, my plan is to find some way to deal with the ridiculous watermarked images or those that contain overlaid text in the training process, as these really seem to be sabotaging the model. I also would like to add a bit more data if possible, maybe for certain artists only, so the model can get a more comprehensive view of what’s going on. I may also add some additional artist categories (although this is optional), and I would definitely like to add a “sister” model that is designed to recognize the artistic era or period of a painting, and use that model to make “backup predictions” of a painting’s era in addition to the artist, in case you give the model a painting that it’s not familiar with. These enhancements should make the Ashryver model much smarter overall as a painting classifier; once I get these improvements done, I should be ready to move onto Unit 3 of the fast.ai Practical Deep Learning course.

    Don’t forget to check out the model on HuggingFace, or go to the AI, ML & Web Projects page to play around with the widget. Stay tuned for more updates!

  • Kaggle Titanic Random Forest Model: Summary and Comments

    Kaggle Titanic Random Forest Model: Summary and Comments

    This month, I finished the final series of hyperparameter tuning and optimization on the Kaggle Titanic Random Forest Model. I constructed this model for the Kaggle Machine Learning from Disaster challenge, which is an introductory-level machine learning prediction competition. Users are supposed to construct a model that predicts whether or not a given person, among 800 people, survived the Titanic shipwreck. This was my first attempt at crafting a new AI model from (close to) scratch, given a fully-featured dataset. Although I probably could achieve higher Kaggle scores by trying out different architectures, I didn’t want to spend the entire year on one challenge, and left the model at a 0.788 public score.

    In this post, I explore some of the code and the inner workings behind the Kaggle Random Forest model. I also dive into a few of the challenges I encountered along the way. If you’d like to work off the model framework I’ve put on GitHub, you can feel free to do that, but I’d strongly recommend against it because I haven’t yet taken the time to make the code fully understandable and customizable. (Also, a serious Kaggle competitor will likely strive for a better model architecture that achieves a higher public score, so please find your own setup).

    Model Setup: From Logistic Regression to Random Forest

    Initially, I started off with a simple logistic regression model loosely based on a Kaggle starter tutorial. For the most part, the tutorial model didn’t involve any careful feature engineering, and primarily relied on the passenger name, class, sex, age, and fare (several of the most important features in the dataset). It used elementary techniques to learn patterns between these features and the survival, and this base model only achieved an accuracy of about 0.74 inside the code cell.

    Immediately realizing that I needed to do more with the model, I switched to a Random Forest architecture, as it seemed to be highly recommended for binary classification problems like this one. The important part about Random Forest is that the model automatically determines which features are the most important, regressing through all the available features in a large “tree”. So I was able to feed it a wide variety of featuers and have it discover the most important connections: the prominent features ended up being Sex, Pclass, and Fare/Age.

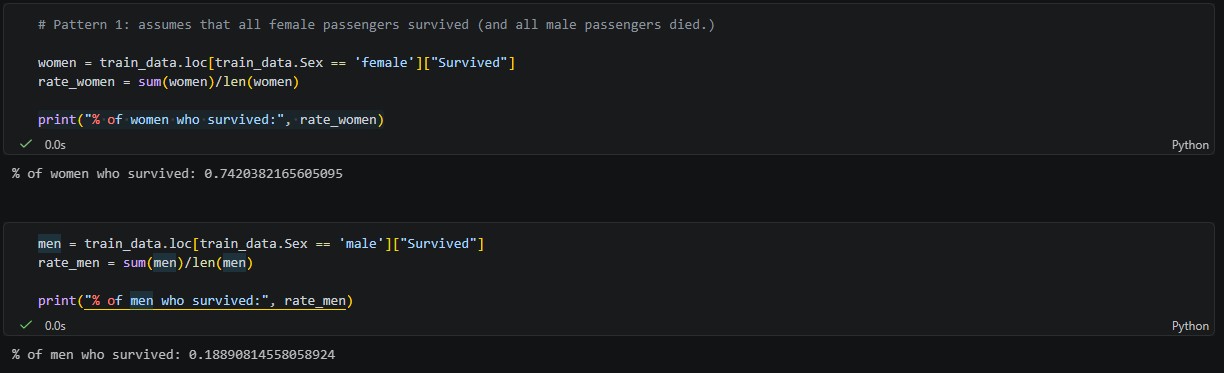
    The percentage of women who survived the Titanic shipwreck (in the sample data) was significantly higher than the percetange of men.

    As shown in the image above, I was able to discover that a significantly higher percentage of women survived than men (74% vs 18%). Historically, this was due to the “women and children first” directive on the ship. I used this basic pattern to train the original model, and the more advanced Random Forest model uncovered this connection as well. I prioritized the Sex feature (in addition to Pclass and Fare/Age) when feeding the features to the model.

    Advanced Feature Engineering: the Cabin Data

    When the Random Forest model based only on Sex, Pclass, and Fare/Age didn’t perform very well, I realized I was going to have to do a lot more feature engineering. After all, the data contains several features, ranging from the number of parents and children aboard the Titanic, to the passenger’s Ticket number, and the cabin number where the passenger stayed.

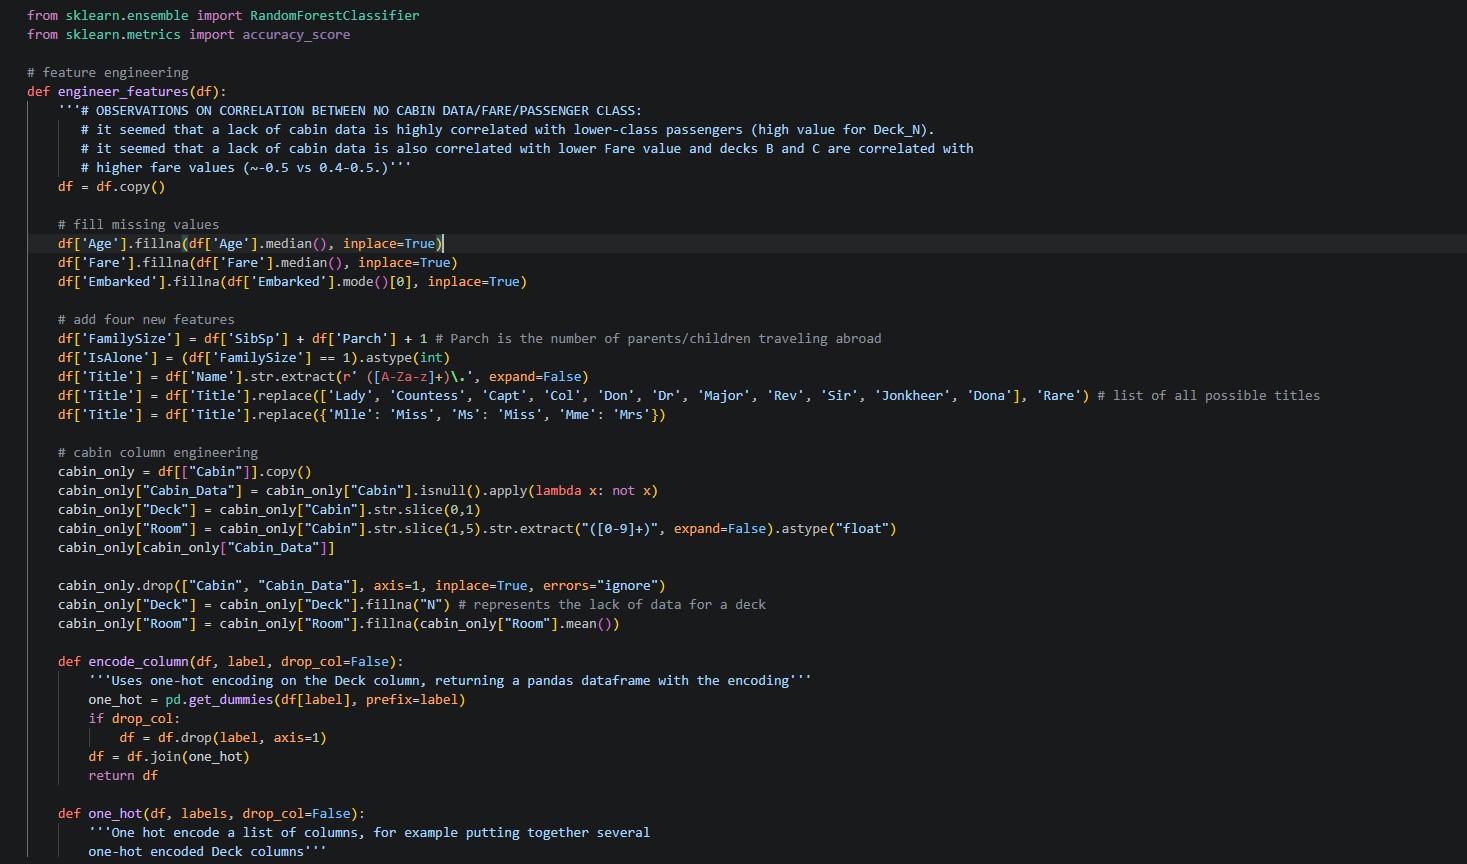
    Since the location of the passenger aboard the vessel seemed like an important data point, I constructed the next round of feature engineering around the Cabin column (and created a few new helpful features from the existing data, like IsAlone or FamilySize). I learned quite a bit about proper feature engineering practices in the process; with the help of Copilot and some Google searches, I was able to construct new engineered data for the model to train on.

    I also built a function to make observations on the correlation between people with no cabin data (we don’t know where they stayed) and passenger class (1st, 2nd, or 3rd class). I wrote these observations at the top of the rather long code cell shown below, and this info actually ended up being helpful in situations where the cabin data was missing.

    A sample of the very long code cell used to engineer the Cabin feature data

    Hyperparameter Tuning (with RandomizedSearchCV)

    After retraining the model with the engineered Cabin data, I was getting much-improved accuracy in the notebook (about 0.82 vs 0.79), but the Kaggle score wasn’t changing. I figured I was going to have to do some more serious hyperparameter tuning to boost the score, which usually only reacts to large-scale prediction changes.

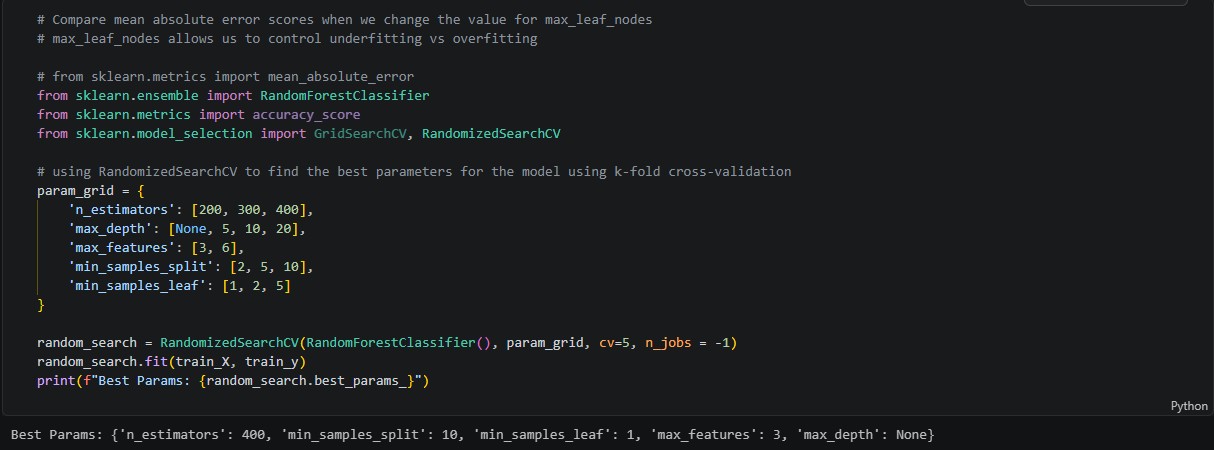
    At first, I attempted to tune most of the important parameters (n_estimators, max_depth, max_features) by hand, doing Google searches to figure out the best values for a Random Forest model. But this quickly became tedious, as I had to retrain the model every time I made a minor change so see if it did anything. Instead, I switched to RandomizedSearchCV, which is an algorithmic method of finding a model’s best parameters povided by the Python library sklearn.

    Using RandomizedSearchCV was relatively simple (as shown in the code cell below). All I had to do was set up a parameter grid, where I told RandomizedSearchCV which hyperparameters I wanted it to optimize. Then, I asked the algorithm to fit on the training datasets of the model, and then output the best parameters using a simple print() statement. From there, I was able to go back and drop in the fine-tuned parameters to the final model. The parameter-discovery process did take a little while, so I had to set n_jobs = -1 to ensure the algorithm ran on all CPU cores.

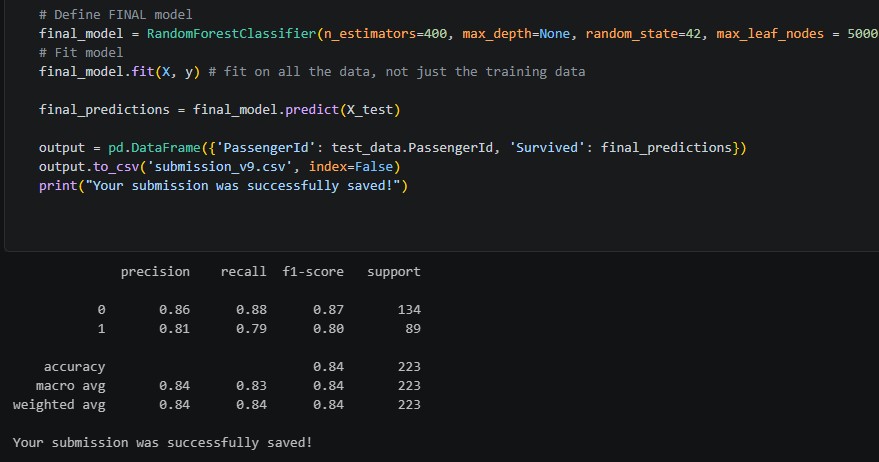
    After the hyperparameter tuning, the model achieved 0.84 validation accuracy in the notebook, and a Kaggle public score of 0.788, which is in the mid-to-upper-tier for these kinds of Random Forest models. I haven’t been able to move above this score since then; however, if I manage to do so, I will update this blog post with those details.

    The model’s final accuracy, precision, and recall report after the final stage of hyperparameter tuning.

    To view this entire Titanic project (and the code files) on GitHub, click here. However, the code is primarily intended for reference, not for drop-in usage in a brand-new project.

  • AI & Machine Learning Project Update: A Fresh Start

    AI & Machine Learning Project Update: A Fresh Start

    Today I returned to the AI & Machine Learning project repository I’d worked on intermittently over the past few months. It’s a GitLab environment with some Jupyter Notebooks and AI projects created on an excursion in summer 2025. I’d managed to make some good progress towards a finished QuickDraw Webcam project last year, but after that, things sort of fell apart. Now, returning to it many months later after system updates and code changes, I found that many of the Jupyter Notebooks (or Stupyter Notebooks, if you will) no longer worked.

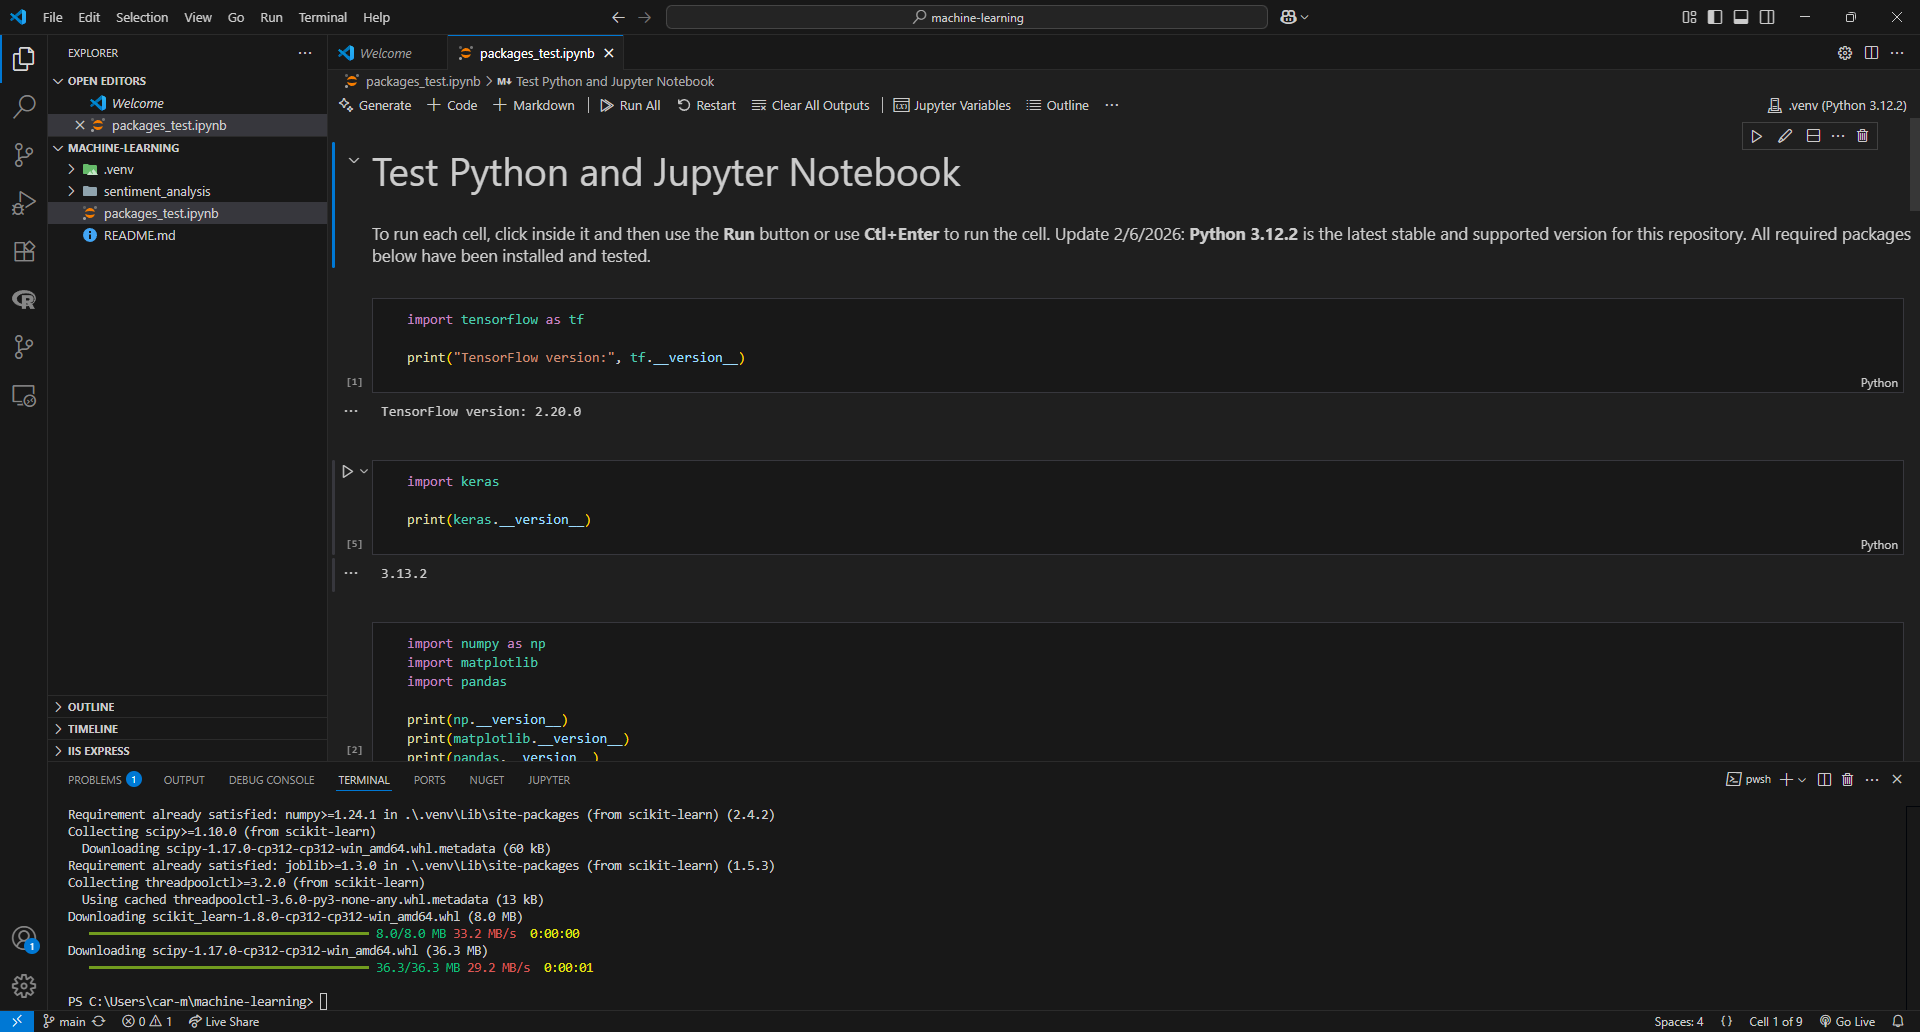
    There were issues like missing packages and unresolved imports, likely arising from the three conflicting Python environments I’d foolishly installed. In general, things were a mess. I first tried switching kernels, enabling the older but sometimes more trustworthy Python 3.11.4. When that didn’t work–and the problems only got worse–I decided to break out the Google Gemini AI, asking for assistance on installing pip (which had mysteriously uninstalled itself from the OS) and getting up to speed on the issues I was experiencing.

    Unfortunately, nothing worked. I ended up having to go through and create a new Python virtual environment in the ai-projects directory, in hopes that it would clear things up a little bit. However, I was dreadfully wrong. The problems again only got worse, and Python threw numerous errors in the terminal upon attempting to run the malfunctioning code cells in the Jupyter Notebooks.

    So I decided to start from scratch. I went to GitHub, logged in, and dug up an old, empty Machine Learning repository I’d created many months ago. Since it was empty, I figured it would be the perfect candidate for a new project. I copied and pasted one of the malfunctioning Jupyter Notebooks from the other environment, and this time decided to set up a new Python virtual environment running version 3.12.2. This was a fresh repository without three different kernels or multiple packages installed, so the virtual environment cleared things up immediately. A virtual environment of Python is separate from the system install on your PC, so I was able to manually install all required AI-related packages without causing corruptions and dependency issues anywhere else.

    And that’s where we are now. I intend to continue working on a product review sentiment analysis model, in which an AI is apparently supposed to predict if a review is positive or negative based on certain keywords. After that, I’ll probably use the repository to explore more advanced AI concepts, possibly with the assistance of an online course. It’s simply supposed to be a general space where I can experiment with machine learning, and so far everything seems to be working. (We’ll see how long that lasts).

    Site Updates & Other News

    I’ve been trying to get some more pages created on this website for the past few weeks. I actually did manage to make some progress on the Short Stories & Poetry page, but WordPress had been acting stupid and I haven’t yet settled on a good design. I’m thinking about simply creating a series of dropdowns containing short story content, but that seems prone to issues and not a very good setup. So, you might find yourself looking at a completely separate blog on that page, or a gallery-style grid of clickable images and media. We’ll just have to see.

    I also started on a wireframe of the concept NoteMaster software, which is supposed to be a high-quality and low-priced alternative to other music notation softwares. The wireframe is coming along in Figma, and it’s going pretty well so far. The trickiest part will be the design of the scoring interface, and this will really test the features in the Figma free plan. (When the wireframe is complete, you can expect to see some prototype design photos on here and the Rustler website).

    With the New York trip over, and no more serious events on the calendar until late March, things are going along pretty smoothly. There are a couple of piano recitals scheduled for mid-April, but other than that, musical activities have slowed down significantly. I’m working on a couple of essay-writing contests and the NowBeat Commission and Concert (form now submitted). Flames of Rebellion: The Reckoning of The Past (book 3.5) is now in review, and the book cover is pretty much done. Progress on book 4 has stalled, but that’s normal for the next book in this series.

    Stay tuned for more information on the AI projects. Hopefully, the virtual environment remains working.